As part of migrating to the latest bazel configurations in #4729, I'm
running into proto toolchain issues. For example:
"Error: <target @@protobuf+//:cc_toolchain> (rule
'proto_lang_toolchain') doesn't contain declared provider
'ProtoLangToolchainInfo'"

Although we may eventually want more use of proto, right now the only
use is for the explorer fuzzer. The explorer codebase is essentially
frozen, so continuing to run it isn't gaining us much (in fact, we've
already disabled autofuzzing for it).

So, rather than trying to fix the proto setup, this change:

1. Deletes `explorer/fuzzing`
2. Removes proto portions of `testing/fuzzing`, which were only in-use
by the explorer
3. Removes some ancillary proto support, which would otherwise break
from the bazel changes and would be difficult to validate as "still
working"

This change is partly isolated in order to make it easier to revive bits
of (3).
The prettier pre-commit mirror is no longer supported
(https://github.com/pre-commit/mirrors-prettier). This switches to a
direct call, and updates to 3.3.3. And I'm now specifying types for it
to apply to, rather than letting it ignore unknown files; overall just
trying to separate out which linter sees what.

To comment on formatting changes:

- In most cases, seems to be getting confused by `[]` use in markdown
when it's not part of a link. This looks like a regression, but not one
we're broadly affected by.
- p0107.md - caught an issue with a malformed broken bad link which I've
tried to fix.
- p3720.md - looks like a fix.

Note, prettier has a 4.0.0 alpha release. As best as I could tell, that
only affected the .prettierrc.yaml processing. I changed the glob there
for forwards compatibility.
Demo site: https://jonmeow.carbon-lang.dev/

I'm trying to keep work under the `/website` subdirectory so that the
misc files don't interfere with unrelated views of the repository. The
`prebuild.py` script does some work to move things around and add
frontmatter, helping the jekyll generation.

I'm using the "just-the-docs" theme because I think it's a decent match
for what we want, and getting jekyll up and running with it wasn't too
difficult. Note #1526 proposed using Docusaurus; I started out there,
but was having trouble getting it working with newer versions. The
plugins in particular I got stuck trying to make work, which sent me
looking for options that we could have working with less customization.
I do lean towards jekyll though, because it's what GH uses so hopefully
we can get a more consistent experience.

Having a website has been approved for a while under #1492, but hasn't
been a priority. I'm mainly doing this because I want to just be able to
point people to carbon-lang.dev and have easy links that way.

---------

Co-authored-by: Chandler Carruth <chandlerc@gmail.com>
VSCode's JSON parser no longer accepts comments in at least textmate
grammars, so remove the comments. It's unclear whether VSCode changed
here or whether this hasn't worked since the comments were added.

Clean up the textmate grammar: refactor, add some missing operators and
keywords, classify keywords as introducer / modifier as appropriate, fix
comment grammar to require space after `//`, and generalize recognition
of iN, fN, uN to recognize all such type literals.

Be more cautious in language server -- I was seeing frequent crashes for
`IdentifierName` parse nodes whose token was not actually an identifier,
presumably due to error recovery.
A lot of the JSON we use is parsed by VSCode or other systems that are
happy to have comments in them, and we should retain a license header
there. We can exclude specific files where this is a problem. I think
the `package.json` and generated lock file from it are two such cases
where we can't have the license header, but we can directly exclude more
as needed.

This should help make sure that when we *do* have a license header in a
JSON file it stays up to date and is formatted canonically.
The usual `pre-commit autoupdate --freeze && pre-commit run -a`

Cutting out a prettier update to v4.0.0-alpha.8 because I'm seeing it
consume all available CPU, basically hanging.
Noticed an unexpected format change in #3850, it's probably because
pre-commit needs to explicitly include def files. The def change here is
a consequence of `pre-commit run -a` with this change.
Support is added for all overloaded operator interfaces in the current
design apart from `Assign`, which is going to require some more work to
properly handle, given that primitive assignment currently has a special
implementation for quite a few builtin types.

As we don't have support for generics yet -- in particular, generic
interfaces -- there is no support for `*With` interfaces, but homogenous
interfaces such as `Add` are supported instead.

Factor out building of call expressions so that overloaded operators can
generate calls.

Switch a few places from using specific kinds of NodeId to a general
NodeId. Because overloaded operators and other things like implicit
conversions can result in member access and function calls, those
operations can't require a specific kind of NodeId.

Add import support for associated entities, and fix import support for
interfaces and symbolic bindings. We now import interfaces in two steps,
first importing a forward declaration then a definition, just like we do
for classes. For symbolic bindings, we ensure that each BindSymbolicName
is imported only once, because its ID is used as its symbolic identity.
This is necessary because we (only) support operator interfaces that are
defined in an imported Carbon package for now.

The entire contents of `check/operator.cpp` should probably be
rethought. In particular, doing a lot of name lookups on each operator
is likely to be bad for performance. But this gets us to the point where
overloaded operators are basically working, which seems like a good
place to iterate from.

For now, the tests that the individual operators map to the right
interfaces are mostly generated by a script, but that's just because I'm
expecting a fair bit of churn in how we define the prelude and the
`impl`s -- in particular, when we add support for `AddWith`, we'll need
to update all the tests. The plan is to remove the script once things
settle down.

---------

Co-authored-by: Jon Ross-Perkins <jperkins@google.com>
Co-authored-by: Carbon Infra Bot <carbon-external-infra@google.com>
The `libpfm` in the Bazel central repository uses `make` to build it,
which is difficult to integrate with our toolchain. Rather than try to
fix all the issues there, it's easy to just add a native Bazel build for
the library. I don't know that any of the relevant upstream folks are
interested in this kind of build, but it seems easy for us to maintain
as a Carbon project build configuration. I've also not tried to port all
of the different configurations as a consequence, and only 64-bit x86
and Arm as that seems the only likely architectures we'll care about in
the near term.

I've kept this using the `bzlmod` stuff as best I can, and I *think* I'm
holding all of those pieces correctly, but if not, happy for suggestions
on adjustments.

The `google_benchmark` package also has an awkward way of enabling
`libpfm` support using a top-level `bazel` command line flag. I think
this is because of how brittle the Bazel build of `libpfm` is, but I'm
not sure. With the new build, it seems easy to patch `google_benchmark`
to detect the same conditions as we build `libpfm` under, and enable it
there. So I've done this to avoid folks having to pass a command line
flag on platforms where it is supported.

The result is that we now get really nice CPU counter support in our
benchmarks out-of-the-box on Linux x86-64 and AArch64. For example on my
Fedora Asahi install on a Mac Mini I get:

```console
$ bazel run -c opt --copt=-gmlt //common:hashing_benchmark --run_under="taskset -c 4" -- --benchmark_counters_tabular=true --benchmark_perf_counters=CYCLES,INSTRUCTIONS
INFO: Invocation ID: 4aaeb9e9-7df5-4f1f-b56b-c03411790268
INFO: Analyzed target //common:hashing_benchmark (0 packages loaded, 0 targets configured).
INFO: Found 1 target...
Target //common:hashing_benchmark up-to-date:
  bazel-bin/common/hashing_benchmark
INFO: Elapsed time: 0.360s, Critical Path: 0.02s
INFO: 1 process: 1 internal.
INFO: Build completed successfully, 1 total action
INFO: Running command line: /bin/bash -c 'taskset -c 4 bazel-bin/common/hashing_benchmark '\''--benchmark_counters_tabular=true'\'' '\''--benchmark_perf_counters=CYCLES,INSTRUCTIONS'\'''
2024-01-15T00:10:50-08:00
Running /home/chandlerc/.cache/bazel/_bazel_chandlerc/b686aa8910e0845b88c21d715819b076/execroot/_main/bazel-out/aarch64-opt/bin/common/hashing_benchmark
Run on (8 X 2064 MHz CPU s)
CPU Caches:
  L1 Data 64 KiB (x8)
  L1 Instruction 128 KiB (x8)
  L2 Unified 4096 KiB (x2)
Load Average: 0.01, 0.08, 0.08
--------------------------------------------------------------------------------------------------------------------------------------------------------------
Benchmark                                                                           Time             CPU   Iterations     CYCLES INSTRUCTIONS bytes_per_second
--------------------------------------------------------------------------------------------------------------------------------------------------------------
BM_LatencyHash<RandValues<uint8_t>, CarbonHashBench>                             4.11 ns         4.11 ns    170200064    13.1321      9.00587      232.116Mi/s
BM_LatencyHash<RandValues<uint8_t>, AbseilHashBench>                             4.82 ns         4.82 ns    145643520    15.3657      12.0059      197.946Mi/s
BM_LatencyHash<RandValues<uint8_t>, LLVMHashBench>                               7.96 ns         7.95 ns     87956480    25.3737      17.0068      119.991Mi/s
BM_LatencyHash<RandValues<uint16_t>, CarbonHashBench>                            4.11 ns         4.11 ns    170365952    13.1247      9.00587      464.573Mi/s
BM_LatencyHash<RandValues<uint16_t>, AbseilHashBench>                            5.51 ns         5.51 ns    127568896    17.5578      14.0059      346.225Mi/s
BM_LatencyHash<RandValues<uint16_t>, LLVMHashBench>                              8.00 ns         7.99 ns     87085056     25.377      17.0068      238.834Mi/s
BM_LatencyHash<RandValues<std::pair<uint8_t, uint8_t>>, CarbonHashBench>         4.91 ns         4.90 ns    136013824    15.6456      14.0059      389.006Mi/s
BM_LatencyHash<RandValues<std::pair<uint8_t, uint8_t>>, AbseilHashBench>         6.85 ns         6.85 ns    102630400    21.8041      18.0059      278.637Mi/s
BM_LatencyHash<RandValues<std::pair<uint8_t, uint8_t>>, LLVMHashBench>           7.57 ns         7.56 ns     92798976    24.1437      20.0068      252.151Mi/s
BM_LatencyHash<RandValues<uint32_t>, CarbonHashBench>                            4.12 ns         4.12 ns    170229760    13.1272      9.00587      926.444Mi/s
BM_LatencyHash<RandValues<uint32_t>, AbseilHashBench>                            4.93 ns         4.92 ns    145304576    15.3738      12.0059      775.224Mi/s
BM_LatencyHash<RandValues<uint32_t>, LLVMHashBench>                              8.11 ns         8.10 ns     87127040     25.373      17.0068       470.98Mi/s
```
This patches bazel_clang_tidy handling of headers. I found an equivalent
change at https://github.com/erenon/bazel_clang_tidy/pull/13, but that
was [already
rejected](https://github.com/erenon/bazel_clang_tidy/pull/13#issuecomment-1047007424).
Per the criticism, this will result in redundant processing of headers.

The project instead uses `HeaderFilterRegex: ".*"`, but that results in
two problems:

1. When running with `-k`, errors are repeated when a header is included
more than once, which is common.
2. clang-tidy including errors from headers that are included from other
modules (e.g., abseil-cpp); filtering correctly is difficult.

Given the trade-offs and options (including forking), I thought patching
was preferable so long as it remains narrow.
Building on #3505, the toolchain and llvm rules require a little more
special-casing to get them to work well. This also moves
libprotobuffer_mutator, but that one's more minor. The migration
encounters more quirks in repo naming as seen by various queries.

This changes some of the toolchain work that was recently done for bazel
7 in #3496, dropping a bzl file I'd suggested to add, instead using
`:all` for toolchain registration. (somewhat as an improvement, somewhat
just to avoid a `load`)

Remaining in the WORKSPACE are example code repos and tree sitter rules.
Neither of these are part of the main toolchain builds, and so will
probably be lower impact if there's a good solution for them.
Some background information is at https://bazel.build/external/migration

Trying to handle the simple cases first. This adds a requirement for
bazel 7 due to differences in bzlmod handling between 6 and 7 (also
discussed on
[#infra](https://discord.com/channels/655572317891461132/707150492370862090/1184942191412510720)).
Bazel seems to be okay with a partial migration such as ths.

The python import behavior has subtly shifted, so `carbon.` is no longer
part of import paths. There's a version-incompatible change for `@@`.
bzlmod makes repos sometimes show as `name~version`.

`target-determinator` seems to be okay with `@@` after a version update.

Things not moved here are things that basically need more dep work:

- clang_register_toolchains because I need to dive into its format.
- llvm-project because we need something slightly atypical, I need to
make sure patching and the repo work carries over.
- com_google_libprotobuf_mutator is sufficiently atypical that it
doesn't have a module already, but should be one of the easier things to
fix.
- brotli/woff2: I think we should actually consider removing these. But
again, they're not trivial moves.
- treesitter due to toolchain registration, which has shifted a bit.
- rules_nodejs because treesitter depends on it in an awkward way to
migrate.
The version of `flake8` was too old to support with Python 3.12 -- there
is new F-string support that caused false positives sadly. The updated
version has fixes for all of these.

This in turn updates codespell which has picked up several new fixes
that actually fire in our code, so also fix everything. While we don't
do more in-depth updates to old proposals, similar to simply fixing
broken links, fixing automatically detected typos seems scalable and
fine.

All edits were automatically generated here.
Also requires switching to using `pip_parse` and providing a fully
resolved requirements lock file. This moves the input requirements to
the `requirements.in` file, and processes it with:

```console
$ bazel run //github_tools:requirements.update
```

This will regenerate the `requirements.txt` file that is checked into
the repository. The advice in the documentation is specifically to keep
this file checked into the repository for hermetic builds with stable
Python dependency versions.

This should fix builds on systems where the Python version is 3.12 and
newer and the older version of `rules_python` stops working with errors
due to removal of long-deprecated interfaces.
The main motivation for this is to get python loads in using the
`native-py` lint fix. However, enabling that made me wonder, maybe we
should fix in general?

`native-cc` is delayed, but not wholly cancelled (and `native-py`
picking up might indicate `native-cc` won't be too far behind). There's
also some automated fixes for `.append` and dict sorting -- this felt
okay to me, maybe not something to eagerly add but probably not worth
stopping buildifier from fixing (I've noticed the warnings in the past
and had been ignoring them).

Running everything does mean that load orders are sorted automatically
now, which I think is a positive. Most generally, I think these fixes
aren't _harmful_, and having them done automatically seems beneficial:
my biggest concern about `native-py` and `native-cc` was actually that
regressions wouldn't be caught, but this addresses that issue
automatically.
Add a language server for carbon as part of GSoC.

This currently does code outline using toolchain parser.

See development steps in utils/vscode/README.md for running and using
language server.
Unused diagnostics were incorrectly always returning "false" regardless of whether there was an issue. It was still looking for registry file changes, not kind file changes. Also, this should only be run once per pre-commit run (pass_filenames=false).

Remove the one unused diagnostic.
pre-commit autoupdate --freeze && pre-commit run -a

This update may be triggering incompatibilities with old installs. If you see an issue such as:

```
An unexpected error has occurred: CalledProcessError: command: ('python', '-mpip', 'install', '.')
```

Try updating pip packages, particularly:

```
pip3 install -U pre-commit
pip3 install -U virtualenv
```
In theory we're doing a central registry so that we can ensure there's at least one test for each. This isn't doing that, but I'm trying to validate that the central registry isn't leading to duplicates or abandoned checks (and catching a couple of each).
Per #2463 we're looking at adding more patches, this updates .pre-commit-config.yaml and sets up the directory structure to be more accommodating to more patches.
Dashes in bazel package names in particular can cause problems (which renaming `llvm-patches` to `llvm_patches` will fix for me). But we've generally named files with underscores, so there's also consistency.
codespell now sees "falsy" as a mis-spelling of either "false" or "falsely"; adding it since I think this it's occasionally used this way in programming. e.g., https://developer.mozilla.org/en-US/docs/Glossary/Falsy

Adjusts to use the new check-copyright support for lines starting with a dash.
PR to add a vim syntax file to support syntax highlighting for .carbon files. Since the Carbon language specification is still in progress, a single syntax file is easier to maintain and adapt to design changes in Carbon. After the language syntax has matured and stabilized, advanced tooling such as Treesitter and Language Servers can take over the syntax highlighting in neovim.
### Highlighting Support
- comments and preprocessors (RUN, CHECK, etc)
- string and numeric literals
- primitive type names, classes, aliases
- control flow constructs
- identifier names
- package and library declarations
- most keywords mentioned in `docs/design/README.md`
### With a Dark Colorscheme:

This image is longer than I thought, so I'm not posting what it looks like in a light colorscheme, but it should look fine as long as vim highlight-groups are properly defined.
Co-authored-by: Jon Ross-Perkins <jperkins@google.com>
TextMate is the go-to definition language for syntax highlighting for editors lack dedicated language support for a given programming language. This patch contains a very minimal, yet functional TextMate bundle definition for Carbon.
This allows Carbon users to import the TextMate bundle into their editors to get basic syntax highlighting for Carbon code until we have a more solid specification for the language (that's when the fun with dedicated plugins/extensions begins!).
**Support**
- String literals with escape codes (currently using C highlighting rules)
- Numeric literals in decimal, hexadecimal and binary (lacks _ separator support though)
- Single and multi-line comments
- Highlighting of all? (let me know if some are missing) keywords in the language
Here is an image of the highlighting in action in IntelliJ Dracula mode
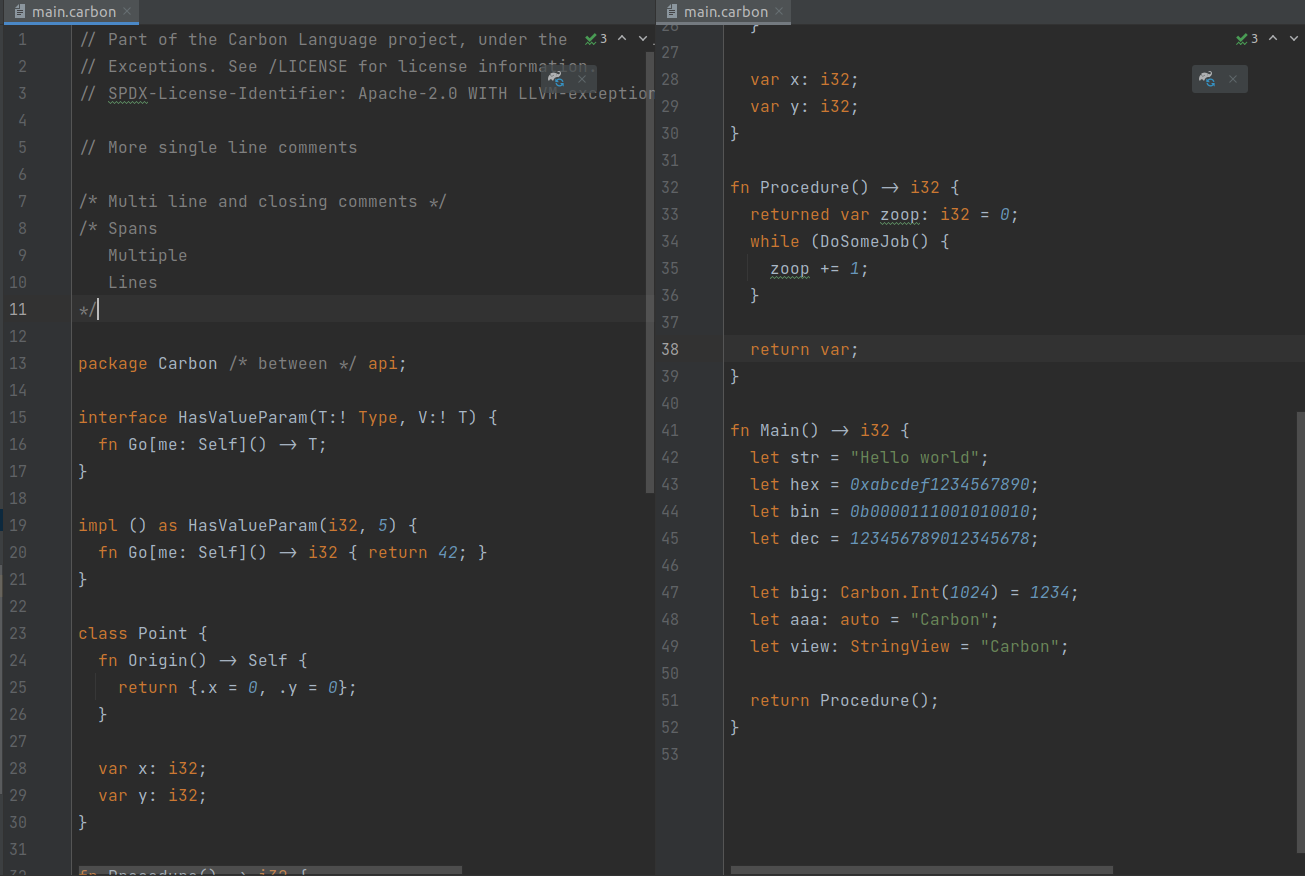
There was unnecessary checking the .svg images (anyway it did not help a lot as mentioned on the #1655#1652 issues).
Regex upgraded so it excludes all .svg.
Tested it on the other files and I think it's correct for now.
This proposal establishes a plan for moving away from the embedded copy
of LLVM and instead downloading it with Bazel.

The goal is that after this lands, we will do a history-rewrite to
cleanup the repository. There are instructions on how folks can move any
in-flight work over to the newly tidied repo.

Co-authored-by: Richard Smith <richard@metafoo.co.uk>
Co-authored-by: Jon Ross-Perkins <jperkins@google.com>
Co-authored-by: josh11b <josh11b@users.noreply.github.com>
This supports aliases for types (including interfaces), functions, parameterized types, instance member names, and interface member names.

Co-authored-by: Jon Meow <jperkins@google.com>
My intent is to add CARBON_ bas a prefix, and this makes that easier by creating a tool for auto-fixing guards in general.

string_literal is a manual fix -- it had no guard and I didn't automate that (technically I think I could, especially by enforcing the file header/footer, but it didn't feel quite worth it to me).
Previous form didn't include *.BUILD or *.bzl files by acceident -- this new form is simpler and more correct, with no issues detected.

Co-authored-by: Chandler Carruth <chandlerc@gmail.com>
 Jon Ross-Perkins

 Sam Estep


 maan2003

 SADIK KUZUandJon Ross-Perkins
 Metarsit
 x2wandJon Ross-Perkins
 Mats Larsen
 Patryk Gutowski
 pk19604014

